Yevgeny.ai
Ask the writing. A standalone, citation-first front door to the published corpus — grounded, cited, nothing made up.
Presentation only — the brain is the shared ask-evgeny worker; this page adds no intelligence of its own.
Don't hope the archive
gets found. Make it answer.
A body of writing is usually a shelf: you publish, you hope the archive gets found. Yevgeny.ai is the other move — make the archive answer. It is a citation-first "ask the writing" destination over the No Fluff corpus: one page where a visitor can ask a question, test a strategy, or trace any claim back to its source.
The pattern is borrowed with attribution: it is inspired by rishad.ai's pattern — personal corpus → conversational front door — but carries the No Fluff visual identity. The same tokens, type, and self-hosted fonts as this site, imported verbatim so they can never drift.
Citation-first is the discipline that separates it from a chatbot. Answers are grounded only in source passages and must cite them; positions, numbers, and opinions are never invented; commercial questions route to a contact CTA instead of improvised advice. And when the corpus doesn't cover a question, it says so plainly.
When the corpus doesn't cover it,
it says so.
One page.
The whole ask experience.
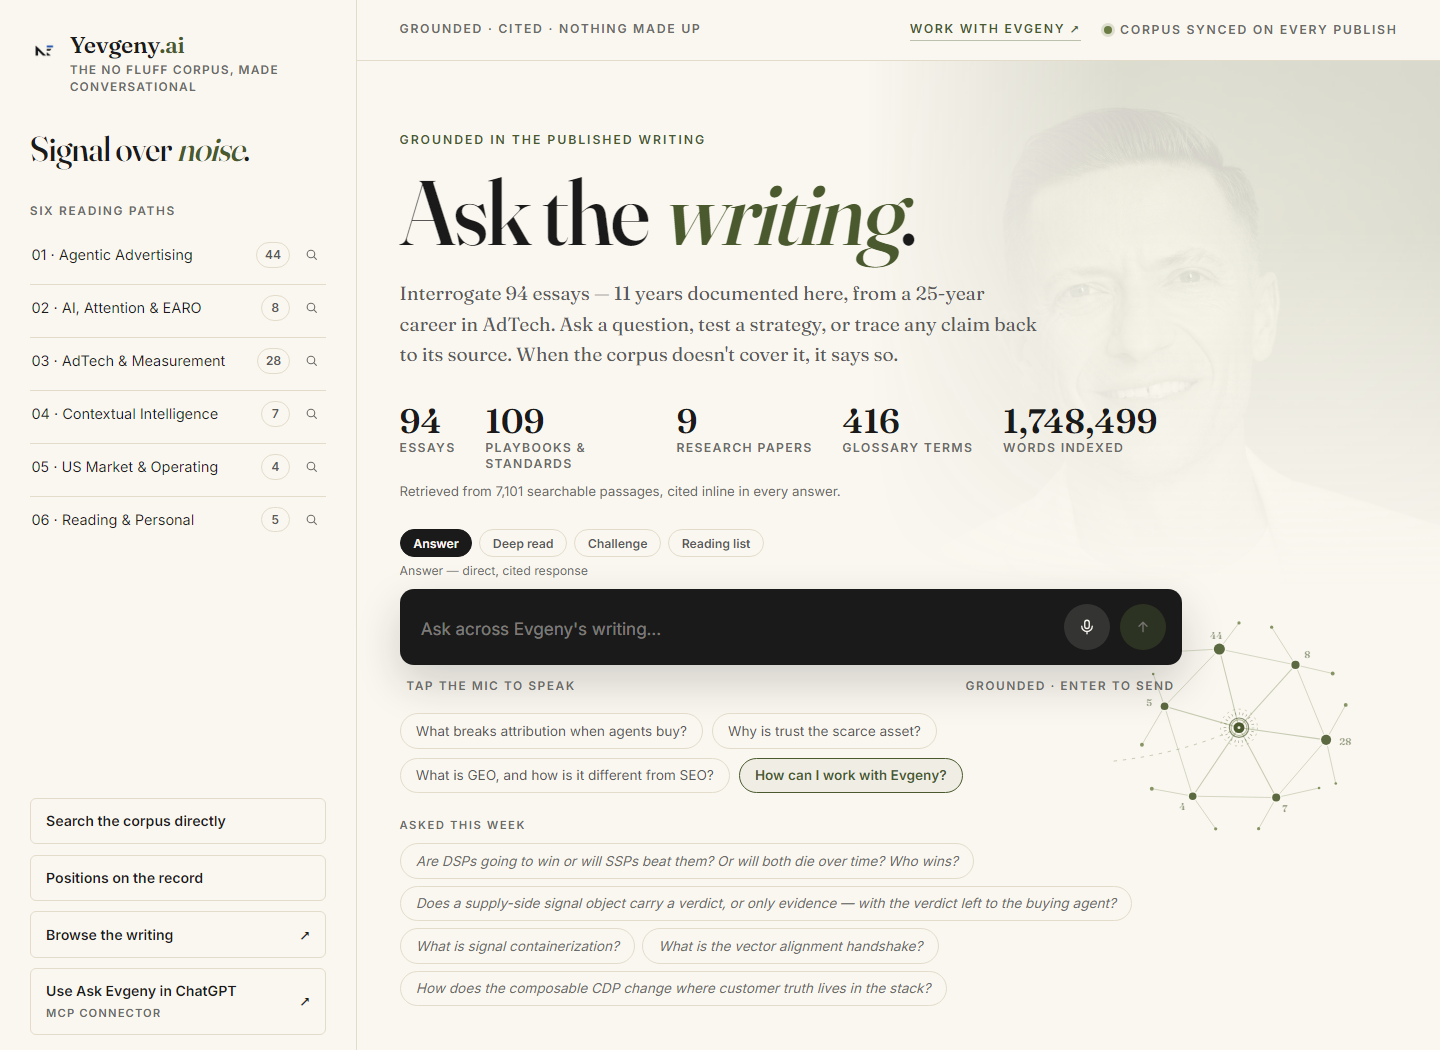
A single page: hero, live corpus stats, the six reading paths, and a grounded, cited ask box with voice input. A two-column frame — left rail with brand, thesis, lenses, CTAs, and the disclaimer — collapses to one column on small screens, where the reading paths become a drawer so the ask experience stays one short scroll away.
It is honest about what it is, twice on the page: an experimental research companion grounded in Evgeny Popov's published writing — it speaks about the work, it is not Evgeny and does not speak on his behalf. Public content only; questions are not sold and never train anything.
-
/api/askGrounded ask box
Dark composer with starter chips and Enter-to-send. Answers come only from passages the hybrid retriever surfaces — when the corpus doesn't cover it, it says so.
-
[n] · source cardsCitations that resolve
Markers in the answer become superscript buttons that scroll to numbered source cards — title, kind, excerpt, and an open-source link.
-
six lensesReading paths
The same six curated topics as the main site, with per-category counts computed at build time, each linking to its topic landing page.
-
build-time statsLive corpus numbers
Essay count, glossary terms, and years-span are computed from the shared sources of truth at every build — never hardcoded.
-
/?q=Shareable questions
Every ask writes a shareable URL; arriving with one auto-submits the question.
-
Web Speech APIVoice input
Push-to-talk mic, shown only when the browser supports it. Recognition fills the input — the visitor still reviews and sends.
-
copy · share · feedbackAnswer actions
Copy with numbered sources, native share, and thumbs feedback tied to an anonymous session id — no PII.
-
staged waitingHonest latency
Waiting messages paced to observed first-token latency; the typewriter reveals only the already-complete, already-filtered answer.
Show all 8Show fewer
One page over one brain.
The question goes to the shared worker's /api/ask endpoint with no page field — the landing itself isn't corpus content — and comes back as a grounded answer whose [n] markers map to numbered source cards. (The worker's KV answer cache only ever serves bare questions — no history, no page.) Retrieval is hybrid: bge-m3 dense vectors and BM25 keyword rank, fused by reciprocal rank, over 7,689 chunks. When a question touches a concept the corpus has taken more than one position on, Position Records fold into the same prompt with authority-bucket tags — classified deterministically from ledger status, never a hand-set flag — and a second check after generation catches any answer that quotes a retired position without saying so. A server-side filter checks answers and citations after generation so unlisted content can never leak.
A governed
evidence system.
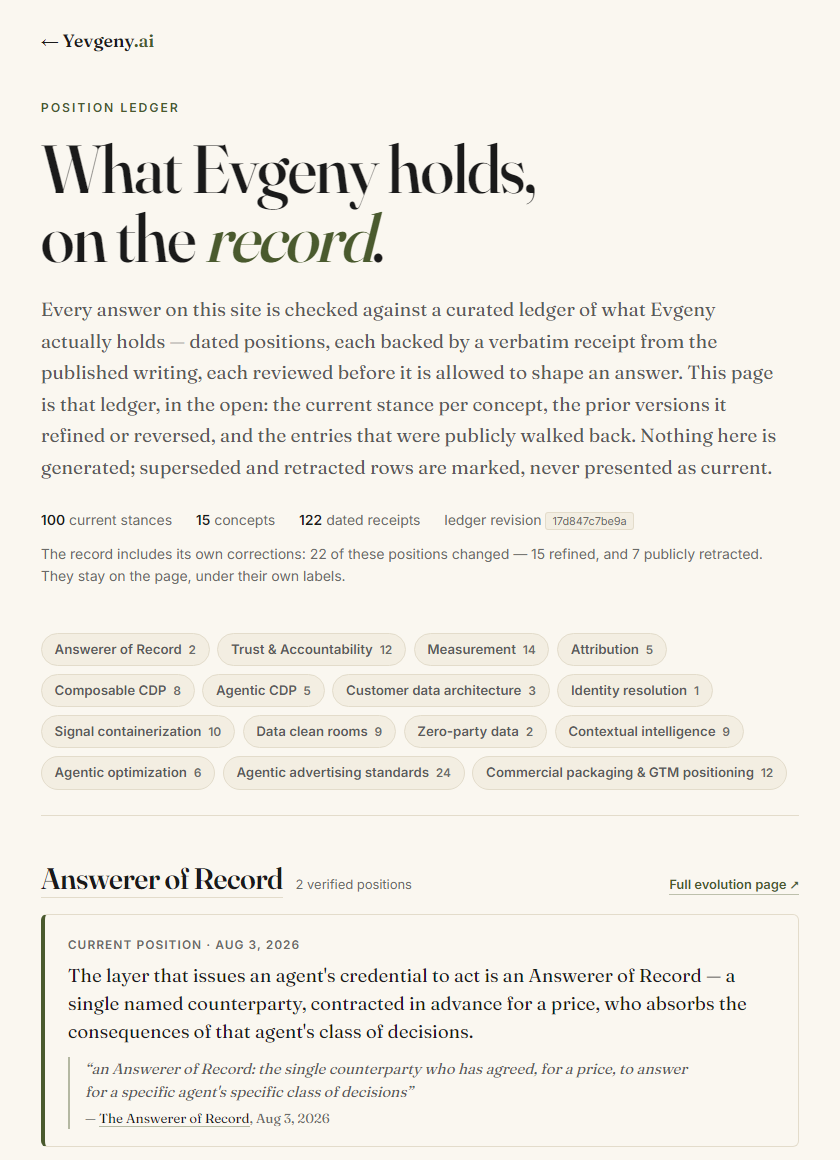
The August 2026 semantic-discovery upgrade turned the brain from a retrieval pipeline into a governed evidence system: the Position Graph now governs retrieval, evidence selection, synthesis, and refusal. Retrieval is hybrid — bge-m3 dense vectors in Cloudflare Vectorize (1024 dimensions) plus D1 FTS5 BM25 keyword rank, fused with reciprocal-rank fusion (K=60) over 7,689 chunks. The chunks were repacked so every chunk's embedding input fits the model's window; previously, chunks up to 6,000 characters embedded only their first 4,000.
Three further upgrades run in shadow: a cross-encoder reranker (bge-reranker-base, depth 15), a one-hop graph retrieval leg with an edge-type allowlist and a per-node degree cap of 25, and a query planner on llama-3.3-70b that produces intent, follow-up rewrites, sub-questions, and glossary anchors. All three run after the response is sent, log to the traces, and change nothing about live ranking until decision gates read the accumulated data. The hand-written regex intent gates stay in place as the degradation path.
The same discipline blocks features. An embedding-space concept atlas failed its own neighborhood-preservation gate — 0.555 measured against a required 0.60 — and ships dark until the projection earns it. The full plan is versioned in the repo at docs/semantic-discovery/PLAN.md.
-
retrieval tracesEvery uncached ask leaves a record
Per-stage latency, per-candidate score decomposition (base RRF score × applied boost), and version stamps for the embed model, generation model, corpus revision, and ledger revision. The store keeps a question hash and length only — raw text never enters it — and traces expire after 90 days.
-
eval gatesA holdout nothing tunes against
A frozen 33-case holdout, stratified from the 174-case golden set, is never tuned against. Every retrieval change must pass hit-rate ≥85%, every leak probe closed, out-of-corpus refusal ≥90%, and the latency budgets.
-
knowledge graph1,145 nodes beside the chunks
408 glossary terms, 414 claims, 125 positions, 98 essays, 61 entities, 24 standards, and 15 concepts, joined by 1,598 typed edges: cites, defines, mentions, supersedes, refines, coins, confirmed-by, redrawn-by. Imported deterministically from hand-curated sources — zero LLM in the import path — and re-seeded on every deploy via hash-diff. Public-only visibility is inherited fail-closed.
-
Position RecordsAuthority buckets, derived
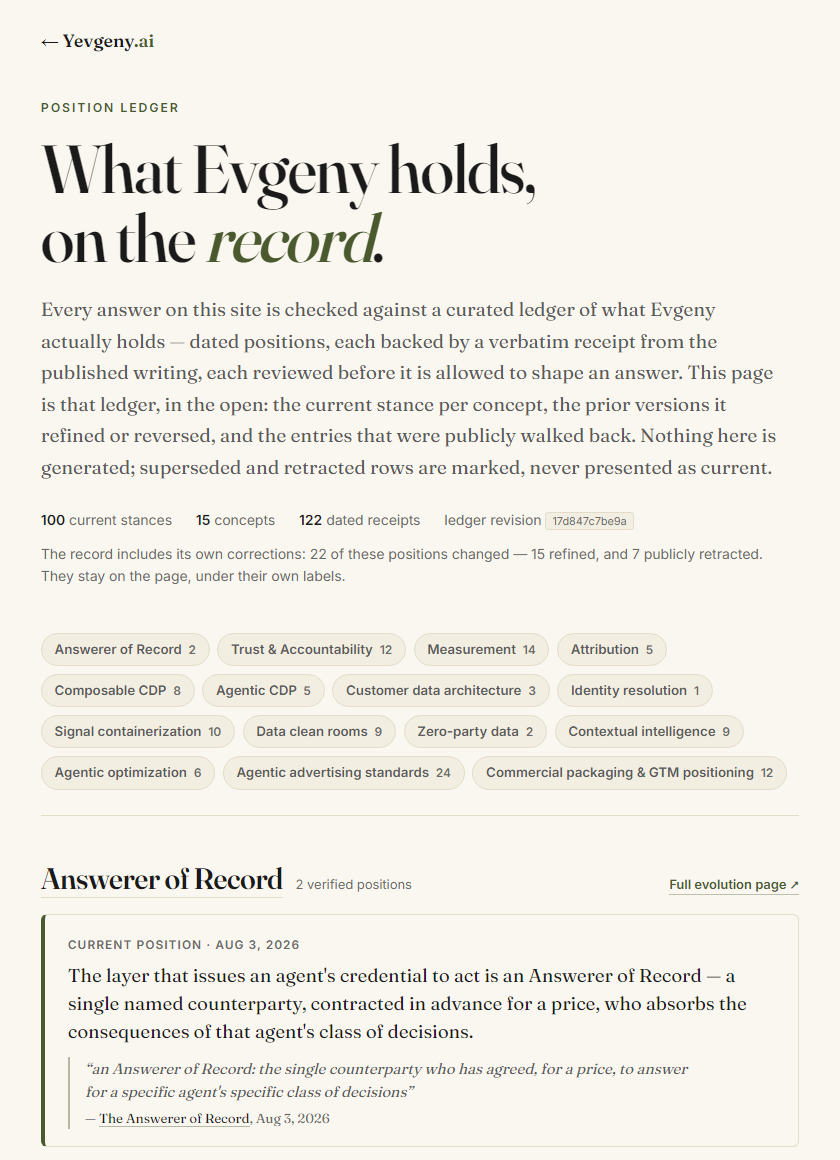
The position ledger grew into Position Records. Ledger status classifies each into current-authoritative, historical, record-only, or internal-only — deterministically, never by hand. Record-only evidence may describe the record but never support a current-view claim; the [POSITIONS] prompt block carries the bucket tags.
-
semantic fingerprintsProximity, not evidence
Every essay page carries its five nearest neighbors by meaning, with cosine scores. The document vector is the chunk centroid blended 0.7/0.3 with a title-plus-synopsis embed, and the fingerprint flags where lexical TF-IDF and vector similarity disagree.
-
MCP · 10 toolsEvidence on the wire
The connector grew to ten tools, adding get_position_evidence — the full evidence record behind one position — and get_mind_changes, the dated supersession chains for anything the corpus has changed its mind about.
Show all 6Show fewer
Presentation only.
The brain is shared.
Presentation only — the honest architectural note from its own README. The brain is the existing ask-evgeny worker at ask.nofluffadvisory.com: the same /api/ask contract, grounding rules, citation mapping, Position Records, and unlisted-leak filter as this site's ask widget. Generation runs on Anthropic (claude-sonnet-5); embeddings stay on Workers AI (bge-m3).
It ships as a second Astro build inside the nofluffadvisory monorepo: its own config with the root pinned to the repo root so the shared essay collection resolves identically, its own src, public, and output directories, and stylesheets inlined at build. Every number on the page — essay count, per-lens counts, glossary terms, years-span — is computed at build time from the shared sources of truth, never hardcoded.
Deploys ride the same GitHub Actions pipeline, sequenced after the main-site deploy so a yevgeny-only failure can never block nofluffadvisory.com: build, ensure the Pages project exists, publish to Cloudflare Pages. The custom domains were a one-time manual step; the worker's CORS allowlist already includes both origins.
- Frontend
- Astro static export · second build in the monorepo (own config, root pinned to the repo root)
- Hosting
- Cloudflare Pages · project yevgeny-ai · custom domains yevgeny.ai + www
- Brain
- ask-evgeny Worker · same /api/ask contract as the site widget
- Models
- Anthropic claude-sonnet-5 (generation) · Workers AI bge-m3 (embeddings) · llama-3.3-70b (shadow query planner)
- Retrieval
- bge-m3 dense (Vectorize, 1024-dim) + D1 FTS5 BM25 · reciprocal-rank fusion (K=60) · 7,689 chunks
- Graph
- 1,145 nodes · 1,598 typed edges · deterministic import, zero LLM · re-seeded per deploy via hash-diff
- Eval gates
- Frozen 33-case holdout · hit-rate ≥85% · all leak probes closed · out-of-corpus refusal ≥90% · latency budgets
- Shared truth
- Essay collection · topics.ts lenses · verbatim global.css import
- Deploy
- GitHub Actions · builds after the main-site deploy on every push
Ask it yourself.
- Production
yevgeny.ai
The destination itself — ask a question, follow the citations back to the writing.
- Cloudflare Pages
Direct Pages URL
The underlying Pages deployment, updated on every push.
- MCP connector
Ask Evgeny MCP
Wire the same brain into ChatGPT, Claude, or any MCP client — ten tools, free key, grounded and cited.
- Essay
Build guide
"Give Your Writing a Brain" — how the shared worker behind this page is built.
- Position Records
Evolution of Thinking
The dated record behind the grounding — every tracked position with its authority bucket, when it changed, and the receipt for each stance.
The practice,
run on itself.
A personal corpus with a conversational front door is becoming a visibility pattern in its own right: instead of hoping AI assistants summarize you correctly, you ship the surface that answers questions about your work — grounded, cited, and on your own domain.
That is the practice No Fluff Advisory sells — AI Visibility & GEO Advisory for AdTech, MarTech, and data companies — and Yevgeny.ai is that practice run on itself: entity engineering, citable content, and machine surfaces, applied to the advisor's own corpus. It is a receipt, not a slide.